Data science course

The Data Science course covers Python, NumPy, Pandas, statistics, machine learning and NLP. Classes are held three times a week, 2 hours each; graduates receive a certificate.

UX/UI design Backend development Digital marketing

Per week:

2

/day

Duration:

3

/month

Age:

18-50

/age

Per week:

4

/hour

Course program

8 topic 54 lesson
01 Python for data science 8 lessons
  1. 1
    Introduction to data science: roles, the project lifecycle and the Jupyter Notebook environment
  2. 2
    Python basics: variables, data types, operators and expressions
  3. 3
    Control flow: conditional statements, for and while loops
  4. 4
    Lists, tuples, dictionaries and sets; list comprehensions and generator expressions
  5. 5
    Functions: parameters, scope and lambda functions
  6. 6
    Handling errors and exceptions: try/except/else/finally
  7. 7
    Modules, packages and the standard library; filtering text with regex
  8. 8
    Classes and OOP: inheritance, polymorphism, decorators
02 Analytics with Python: NumPy, pandas and visualization 8 lessons
  1. 9
    NumPy arrays: indexing, slicing and vectorized operations
  2. 10
    pandas: Series and DataFrames, importing and exporting files
  3. 11
    Combining data: merge, concat and join types
  4. 12
    Data cleaning: missing values, duplicates and type conversion
  5. 13
    Transforming data with pandas: groupby and pivot_table
  6. 14
    Exploratory data analysis (EDA)
  7. 15
    Visualization with Matplotlib and Seaborn: line charts, histograms, box plots, scatter plots
  8. 16
    Module project: an analytical report for education programs and the HR department
03 Statistics for data science 9 lessons
  1. 17
    Data types, populations and samples, sampling methods
  2. 18
    Descriptive statistics: mean, median, mode, variance and standard deviation
  3. 19
    Entropy and information gain
  4. 20
    Probability: conditional, joint and marginal probability, Bayes' theorem
  5. 21
    Probability distributions, the normal distribution and the central limit theorem
  6. 22
    Statistical inference: point estimates and confidence intervals
  7. 23
    Hypothesis testing: parametric and non-parametric tests, the t-test, p-values
  8. 24
    Experiment design and A/B testing
  9. 25
    Correlation, covariance, causation and Simpson's paradox
04 Introduction to machine learning and regression 5 lessons
  1. 26
    What machine learning is: categories, workflow and scikit-learn
  2. 27
    Train/test split and model evaluation
  3. 28
    Linear regression and gradient descent; MAE, RMSE and R² metrics
  4. 29
    Logistic regression; WOE and IV
  5. 30
    Collinearity, residual analysis, heteroscedasticity and homoscedasticity
05 Supervised learning: classification algorithms 8 lessons
  1. 31
    Decision trees and the confusion matrix
  2. 32
    Random forest and feature importance
  3. 33
    The Naive Bayes classifier
  4. 34
    Support vector machines (SVM)
  5. 35
    Classification metrics: precision, recall, F1, ROC-AUC
  6. 36
    Model selection: cross-validation, Grid Search and Random Search
  7. 37
    Boosting: AdaBoost, XGBoost and LightGBM
  8. 38
    Feature engineering: encoding categorical variables, scaling and Pipeline
06 Unsupervised learning and dimensionality reduction 4 lessons
  1. 39
    Clustering: K-Means and choosing the optimal number of clusters
  2. 40
    Hierarchical and C-means clustering
  3. 41
    Dimensionality reduction: PCA and factor analysis
  4. 42
    Linear discriminant analysis (LDA)
07 Natural language processing (NLP) 7 lessons
  1. 43
    Introduction to text mining and NLP: the NLTK environment and corpora
  2. 44
    Text preprocessing: tokenization, n-grams and stop words
  3. 45
    Stemming, lemmatization, POS tagging and NER
  4. 46
    Sentence structure analysis: syntax trees, chunking, CFG
  5. 47
    Text vectorization: Bag of Words and TF-IDF
  6. 48
    Text classification with scikit-learn: Multinomial Naive Bayes
  7. 49
    Module project: sentiment classification of movie reviews
08 Final project 5 lessons
  1. 50
    Business case: exploring and visualizing car insurance data
  2. 51
    Data wrangling: imbalanced data, One Hot Encoding, Standard Scaler and Min Max Scaler
  3. 52
    Modeling: PCA, logistic regression, Linear SVC, XGBoost and AdaBoost; F1 score
  4. 53
    Saving the model (joblib) and building a demo interface with Streamlit
  5. 54
    Final project presentation

Our instructors

Meet our experienced teachers!

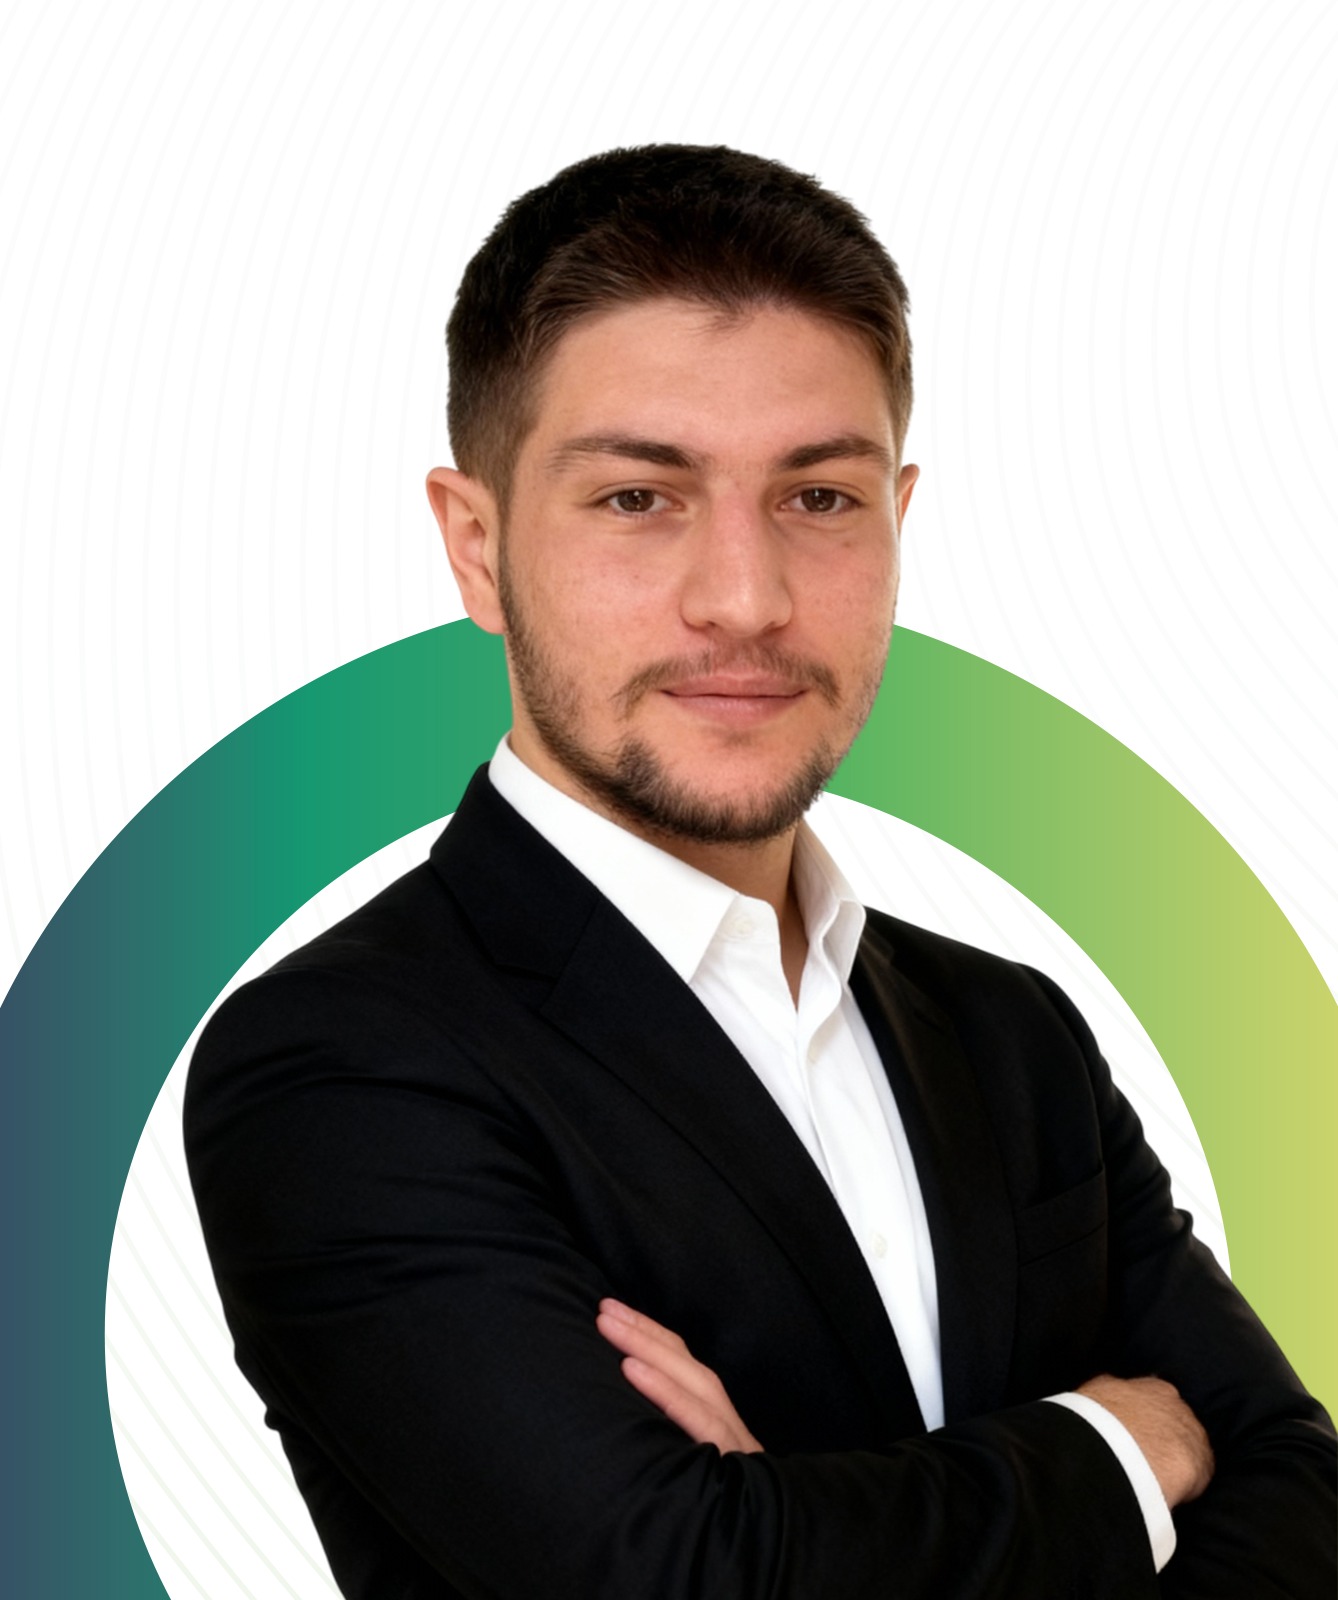
  • Uğur İmaməliyev — instructor

    Uğur İmaməliyev

    Data science course

    Don't know where to start?

    Not sure where to start?

    Get free advice

    Fill in the details and we'll get in touch with you.

    +994

    Your data is used only to contact you.

    Contact us directly (+994 10) 234 65 56
    CourseData science course
    • Address
    • 609 Jafar Jabbarli St., Baku / Globus Center

    • Social networks